

GPU CAPACITY
8GPUs
Capacity aligned to your model
Eight GPUs per HGX node support the demands of your training or inference workload.
THE AI FACTORY FOR YOUR NEXT LEAP
Train ambitious models, generate and use AI tokens, and run inference in production. TensorBay AIFactory brings NVIDIA GPU systems, high-speed networking, and storage together to support that work.
Start with 8 GPUs from $19.50/hr · yearly reservation
 DeepSeek
 Llama
 Qwen
 Kimi
The infrastructure behind AI token generation and use
From model to production, every layer has a role.



02The TensorBay advantage
GPU systems, cluster readiness, and clear pricing work together to move models from training to production inference, with costs in view.
Eight-GPU HGX nodes give models dedicated compute for training and inference.
Before handover, the cluster is checked under load across memory, network, and thermal behavior.
Published rates and per-minute metering within your reservation help you plan each production run.
BUILT FOR THE WORK
TensorBay AIFactory brings compute, networking, storage, power, cooling, and operations together around the work, supporting the full cycle from model training through token generation and use to production inference.
 TENSORBAY AIFACTORY
Compute is reserved around your model, data path, and delivery window. Networking, storage, and operations are planned alongside the GPU systems.
Network, storage, and acceptance testing are planned together so your team has a clear path from first run to production capacity.
03The Token Factory at work
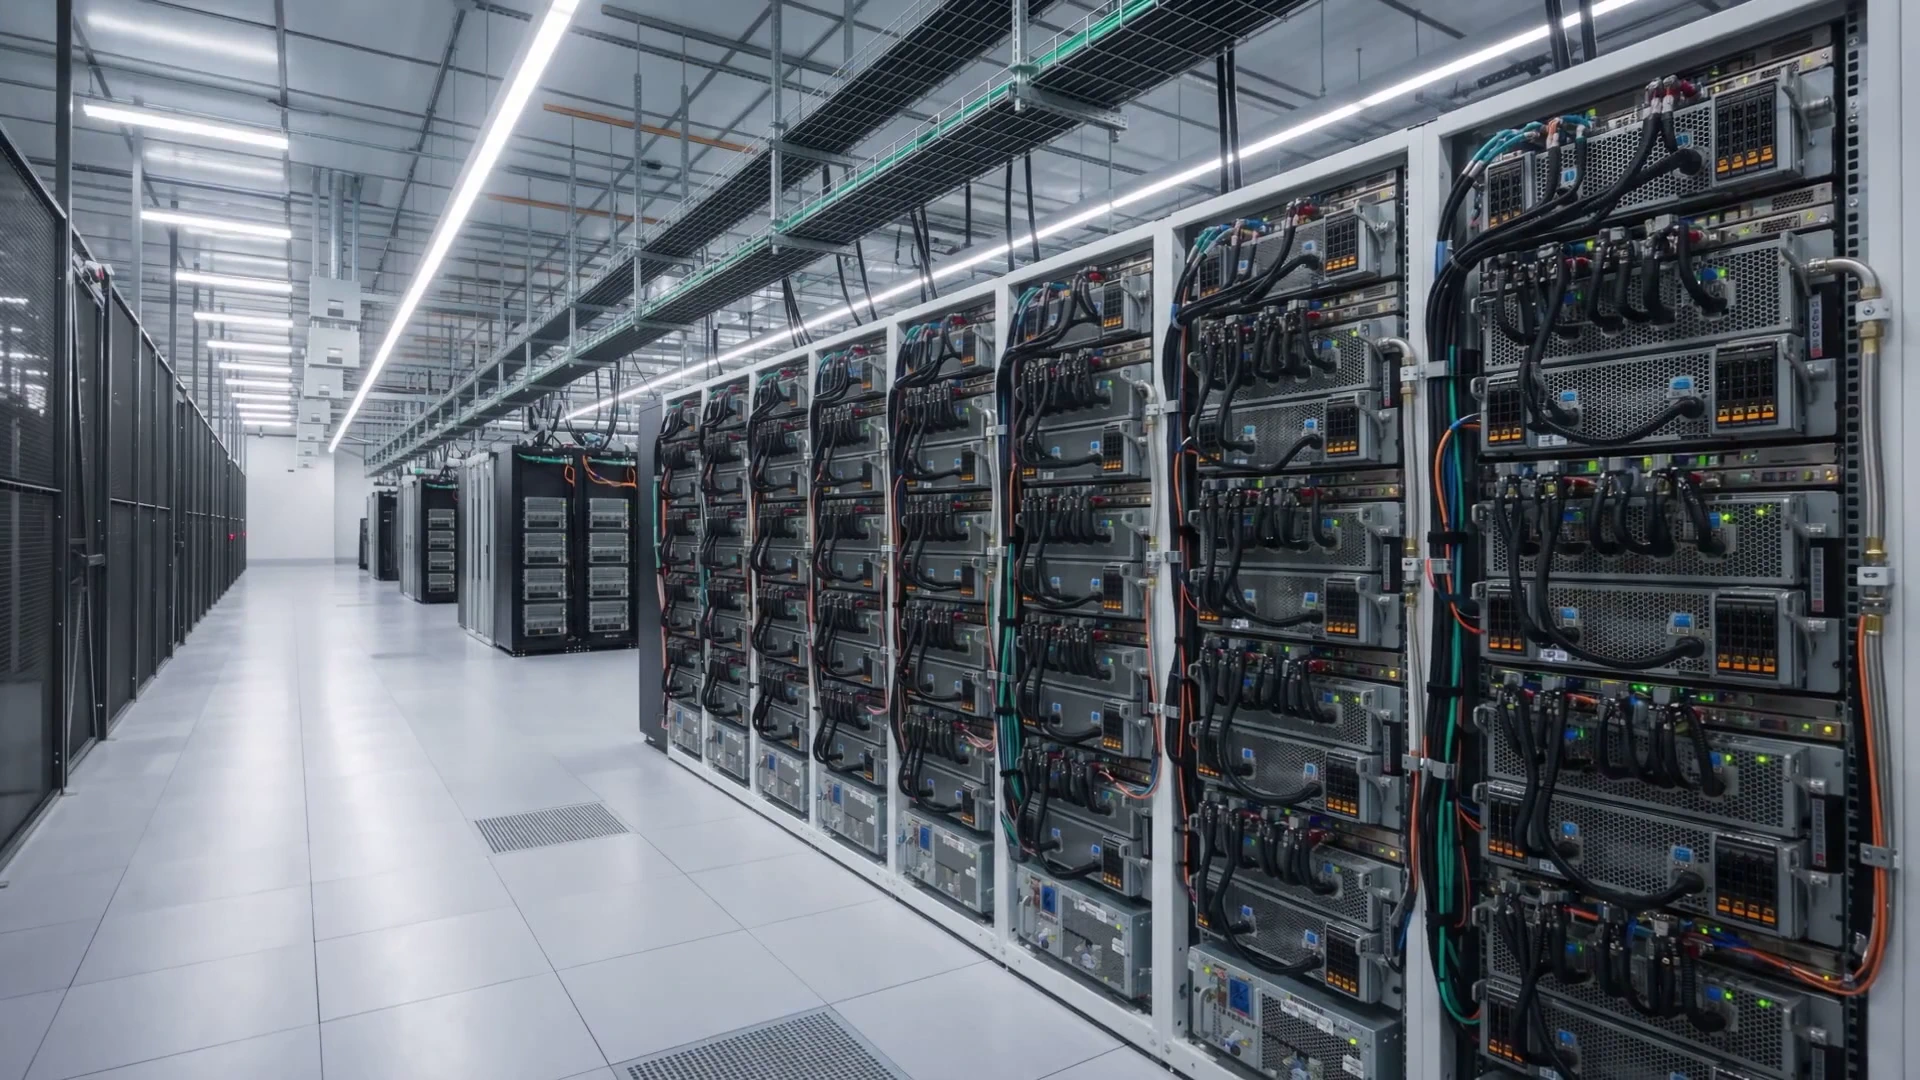
TensorBay AIFactory brings power, cooling, GPUs, and networking together to support the full AI workload cycle, from model training through token generation and use to production inference.
PUE 1.12
Direct-to-chip liquid cooling in 130 kW racks, designed for intensive AI workloads.
24,000+ GPUs
Capacity expands in six-week cycles, with readiness checks before each handover.
97.4%
Cluster goodput over the last 90 days measures how much capacity became useful work.
INSIDE TENSORBAY AIFACTORY
NEVER BUILD ALONE
Bring your model, capacity goals, and timeline. TensorBay’s team can help shape the configuration and next steps.
Talk to sales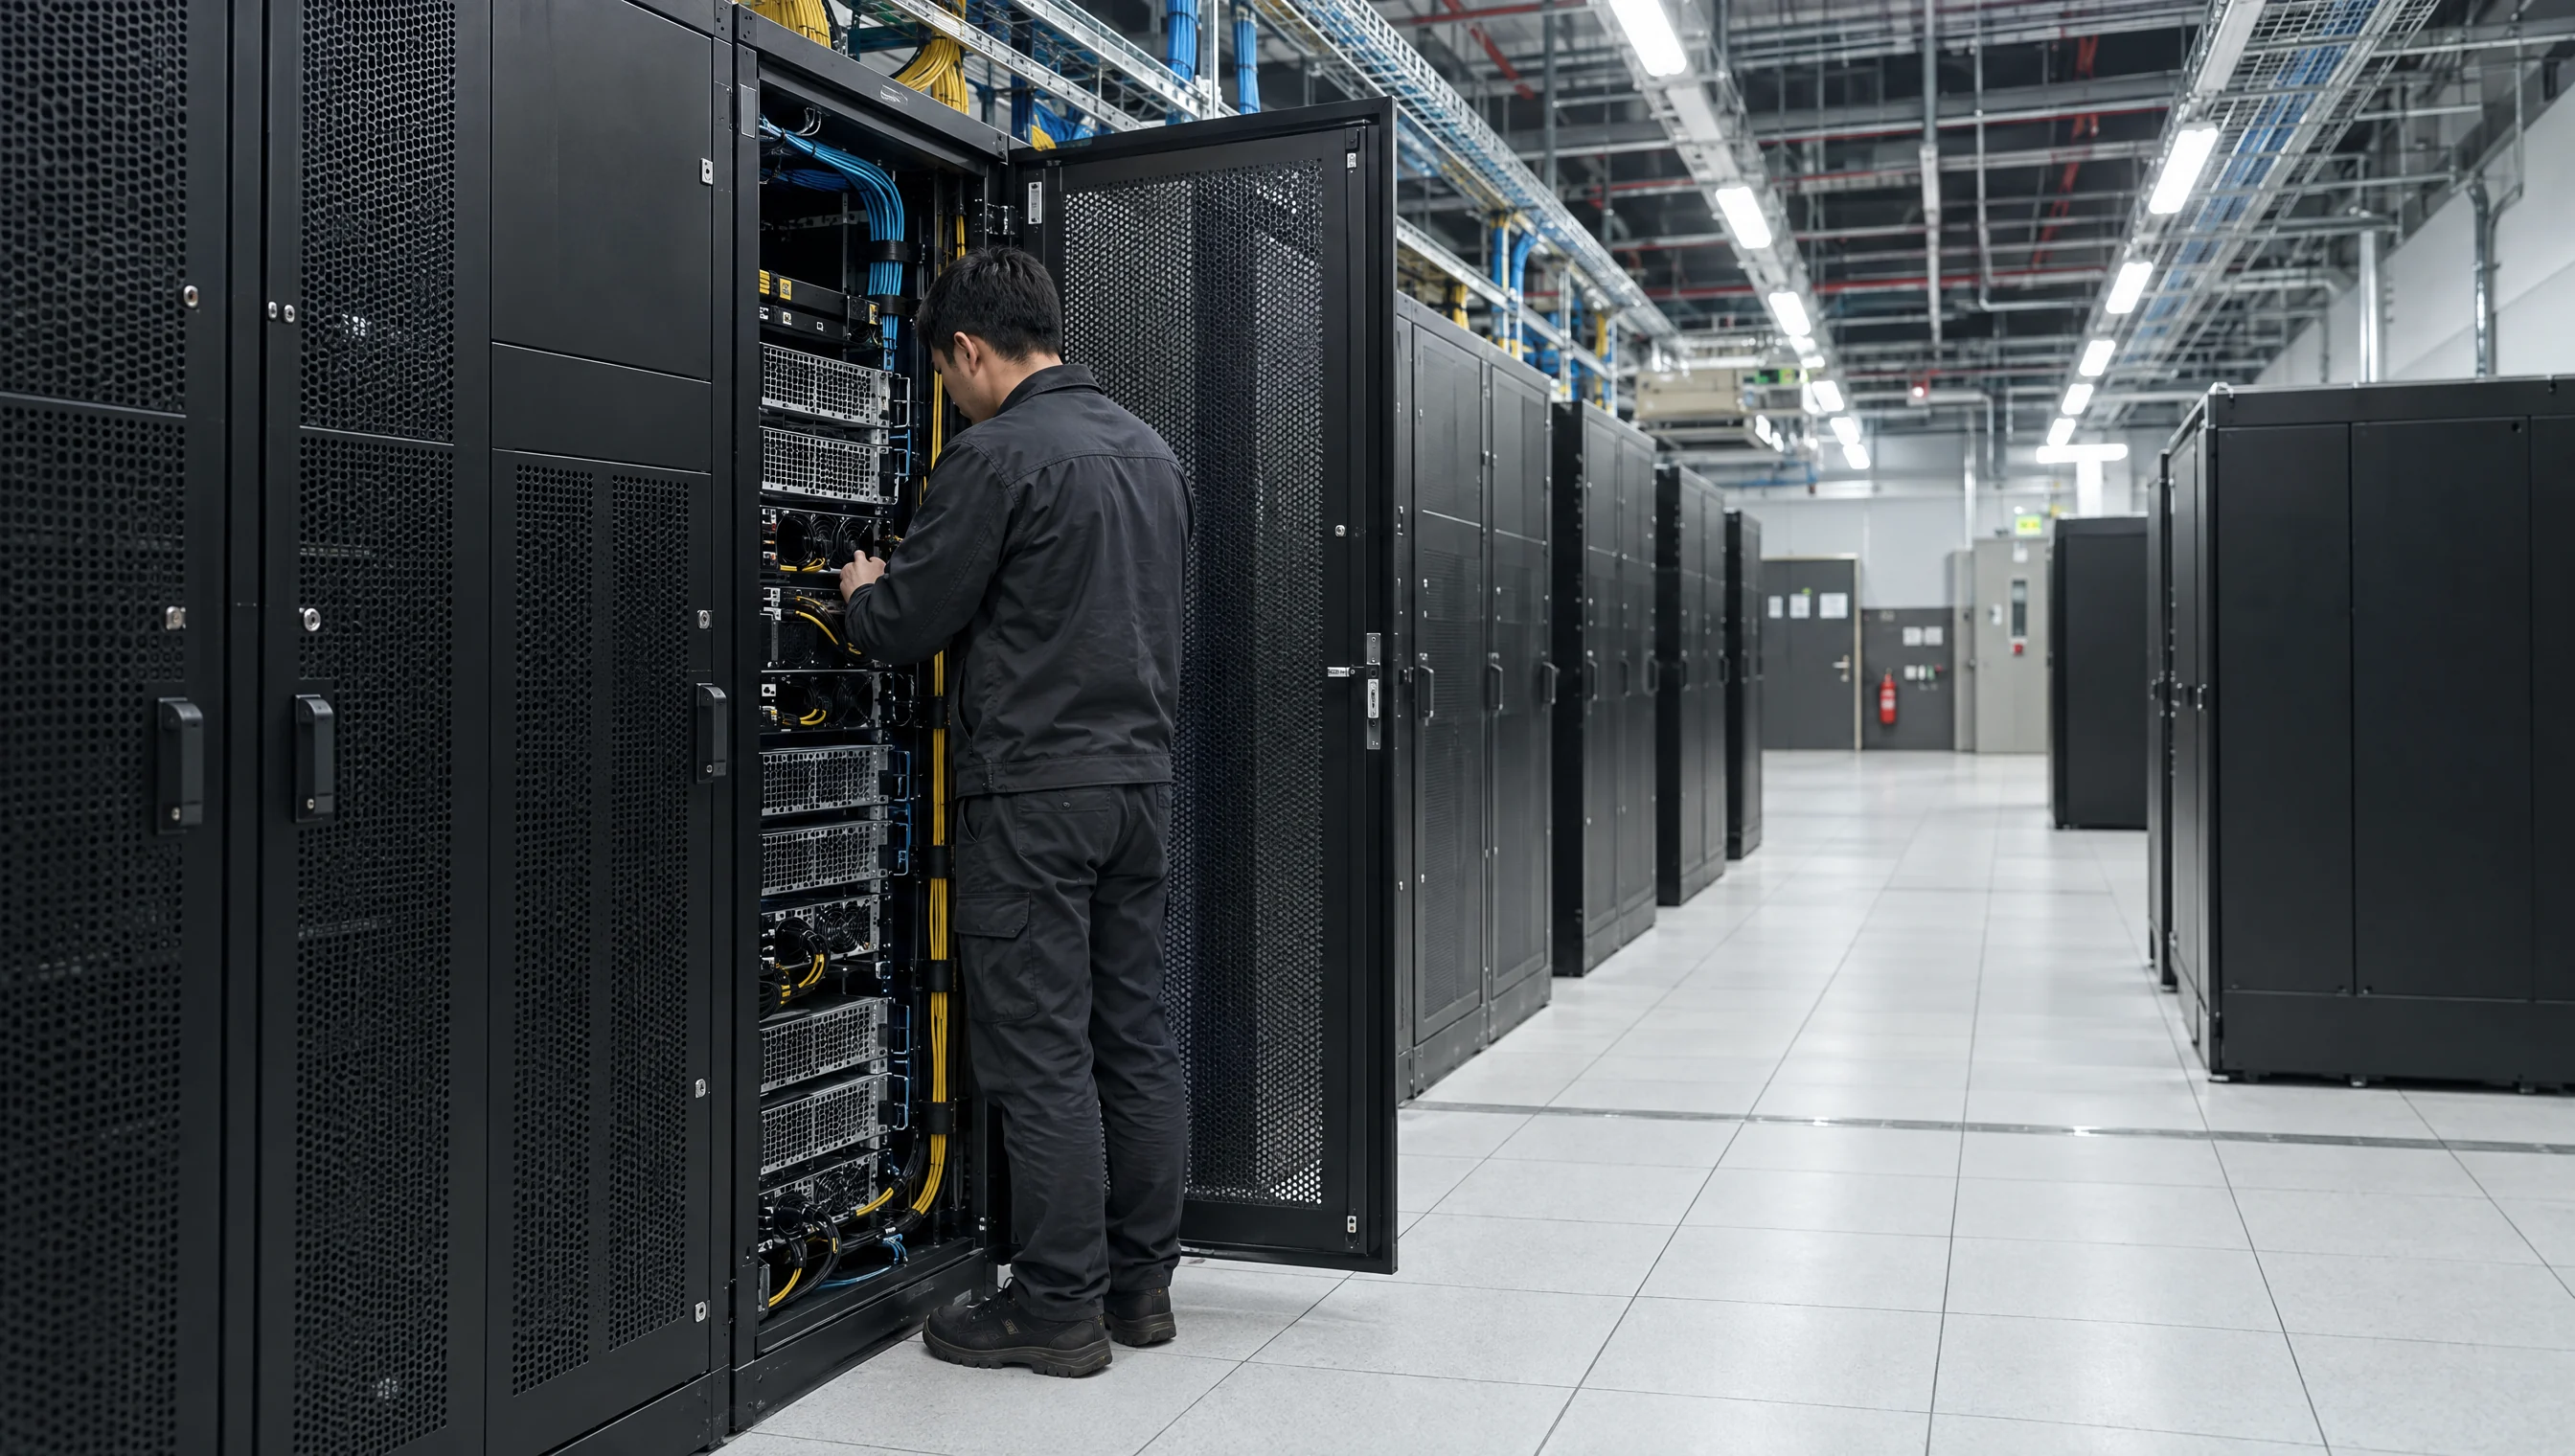
TESTED BEFORE HANDOVER
Every cluster receives load, memory, network, and thermal acceptance tests. Your team reviews the results before approving delivery.
Load · memory · network · thermal checks
AI WORKLOADS
EXPLORE THE AI FACTORY
Go beyond the GPU. Explore how token economics, infrastructure, and the path from model to production fit together.

TOKENOMICS
See how model choices, compute utilization, and application demand interact through generation and use.
What shapes token economics in production?
AI FACTORY
See how GPU compute, power, cooling, networking, storage, and operations come together around your workload.
One system behind every production workload.DATA PATH
Plan high-speed networking and storage around the data path your training and inference workloads depend on.
Keep models and data moving together.08Give your idea room to grow
Bring us your challenge. Our team will help define your GPUs, capacity, and timeline. Get a proposal within 48 hours to launch your project or take it further.


